
SeoSpidie
See your site the way search engines do
Check whether your robots.txt allows or blocks the crawlers that power ChatGPT, Claude, Perplexity, Google's AI features, and more — then generate a starter llms.txt file, a proposed standard for pointing AI systems at your most important pages.
Enter a domain and press Enter. We read only your public /robots.txt.
Upload this as /llms.txt at your site's root (same level as robots.txt). It's an emerging, not-yet-universal convention — some AI systems already fetch it, most don't yet, so treat it as a low-cost bet on where things are heading rather than a guaranteed lever.
AI crawlers are bots run by AI companies to fetch web pages. Some collect content that may be used to train models; others fetch pages to answer a user's question or to build an AI search index. Examples include GPTBot and OAI-SearchBot from OpenAI, ClaudeBot from Anthropic, PerplexityBot, and Google-Extended, which controls use of content for Google's AI models.
Because each company publishes separate user-agent names, site owners can allow some uses and block others in robots.txt. A publisher might block training crawlers but allow search crawlers so its pages can still be cited.
llms.txt is a proposed standard — a simple Markdown file at the root of a site — that points AI systems to a site's most important pages with short descriptions. It is new and not universally supported, but it is easy to add.
AI assistants learn from and quote the web through their own crawlers — GPTBot, ClaudeBot, PerplexityBot, Google-Extended and others. Your robots.txt decides which of them may read your pages, and many sites block or allow them by accident because a broad rule written years ago now matches bots that did not exist then.
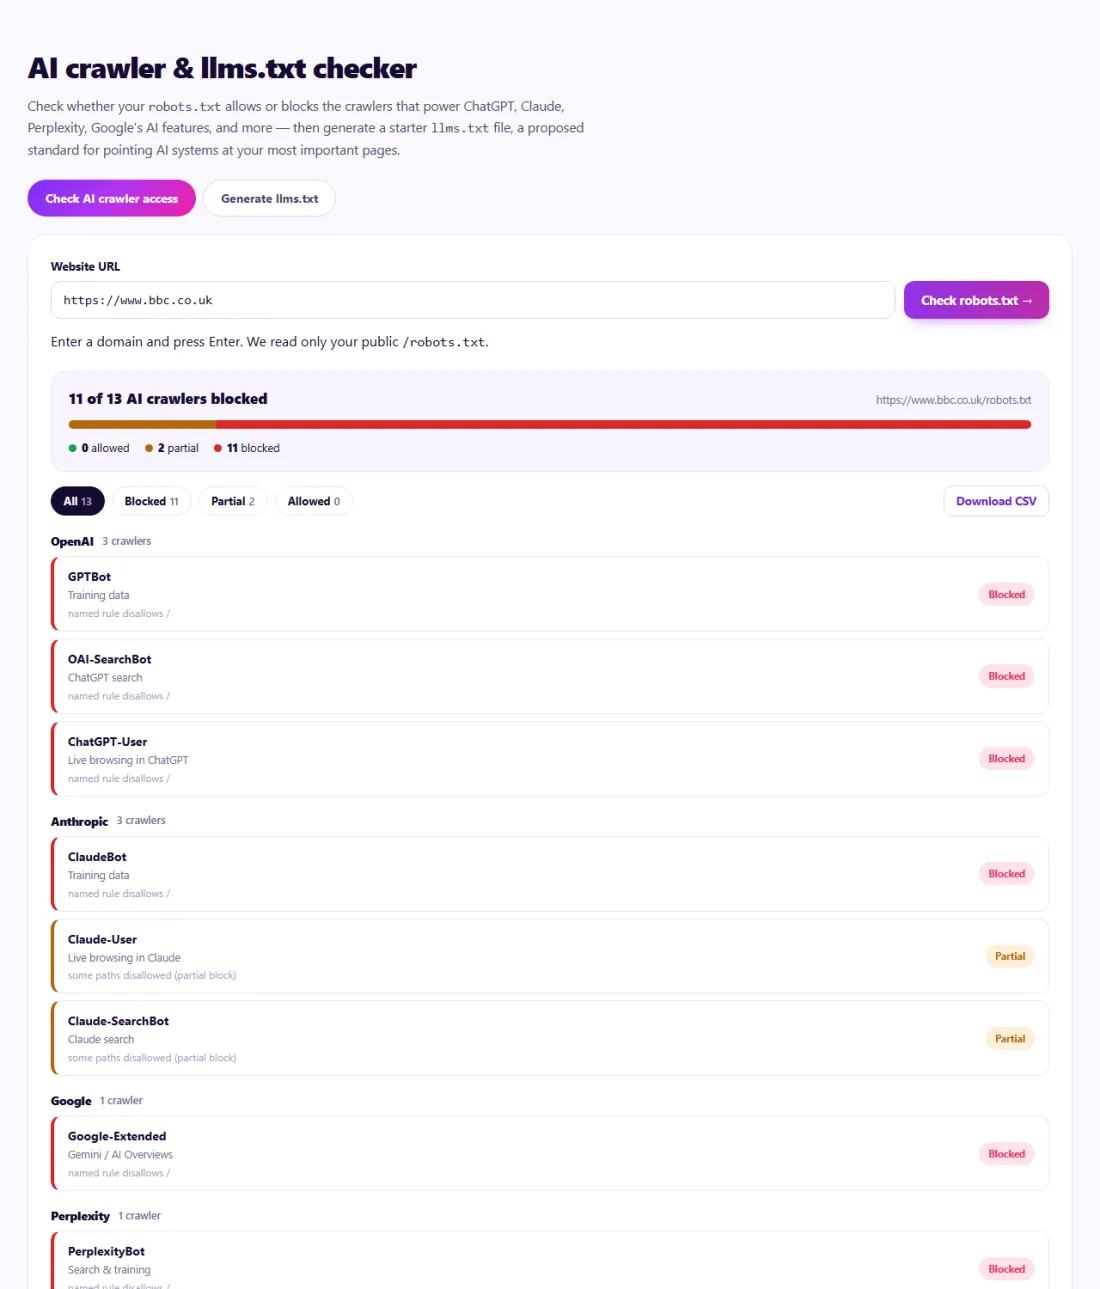
Review each bot and decide whether its result matches your intention. If a search-related crawler is blocked by accident, find the rule responsible and change it. If you want to block training use only, block those agents specifically rather than every bot.
Remember that robots.txt is a request respected by well-behaved crawlers; it is not access control.
A news site in Ireland wanted to stop its articles being used to train AI models but still appear as a cited source in AI search answers.
The AI Crawler Checker showed that its robots.txt blocked every listed bot with a single wildcard rule added years earlier. Using the suggested rules, the site blocked training-focused crawlers by name and allowed search-related ones. It also published a starter llms.txt pointing to its main sections. The checker then showed exactly the split the editors intended.
It stops OpenAI's training crawler from reading your pages going forward. Content already collected and answers built from other sources are not affected, and ChatGPT's live browsing uses a separate user agent.
A proposed plain-text file at your site root that gives AI tools a concise overview of your site and its key pages. It is optional and not an official standard, but it is cheap to add.
No — it is a voluntary convention. The major AI companies say their crawlers respect it, which is why it is the main control available to site owners.
OpenAI uses GPTBot to collect content that may be used for training, and OAI-SearchBot to find pages for ChatGPT search. You can allow or block each separately.
Blocking AI-only crawlers does not affect Googlebot. Google-Extended controls AI use of content and is separate from search crawling.
To read other websites, SeoSpidie's server fetches the public URLs you enter and sends the result back to your browser. We don't keep your reports or require an account. Text you paste stays in your browser. Fair-use limits apply to protect the service.
Yes. The AI Crawler & llms.txt Checker is free to use with no sign-up. SeoSpidie is supported by advertising.
 AI Overview OptimizerOptimize content for visibility in AI-powered search results.
 GEO CheckerAnalyze geographic and location-related SEO signals.
 Featured Snippet OptimizerStructure your content for better featured snippet opportunities.
 Blog Topic GeneratorGenerate useful, search-focused blog topic ideas.