SeoSpidie
See your site the way search engines do
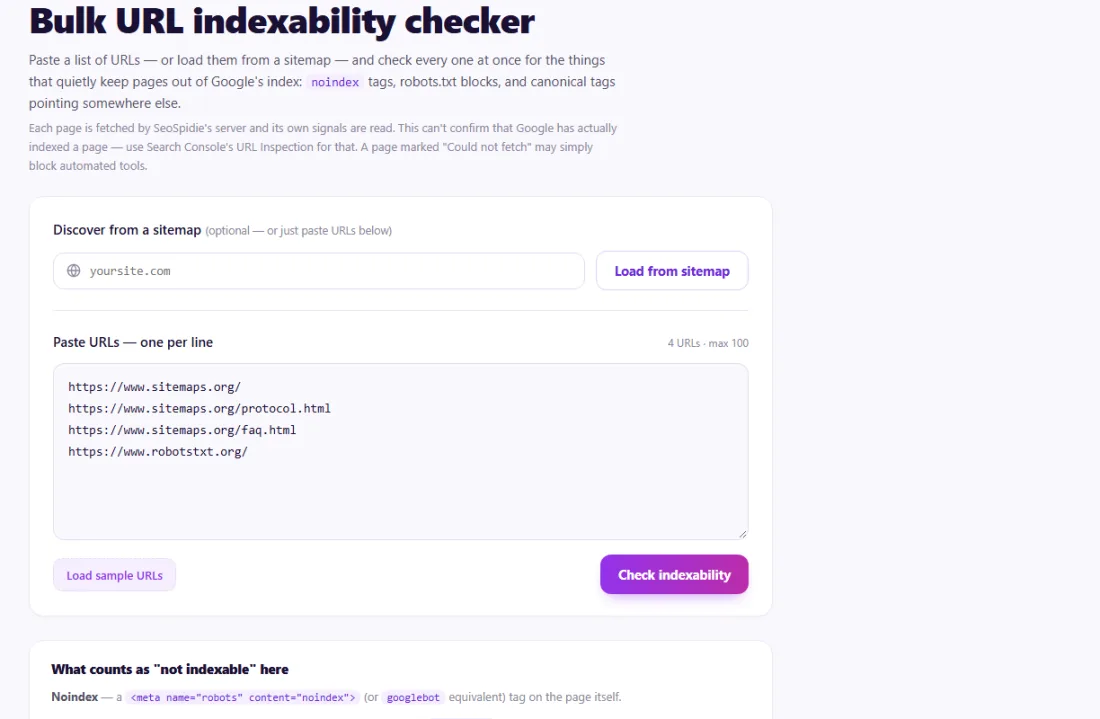
Paste a list of URLs — or load them from a sitemap — and check every one at once for the things that quietly keep pages out of Google's index: noindex tags, robots.txt blocks, and canonical tags pointing somewhere else.
Each page is fetched by SeoSpidie's server and its own signals are read. This can't confirm that Google has actually indexed a page — use Search Console's URL Inspection for that. A page marked "Could not fetch" may simply block automated tools.
A page is indexable when search engines are allowed to add it to their index and show it in results. Several technical signals decide this. The page must load with a normal 200 status code; robots.txt must allow it to be crawled; it must not carry a noindex directive in a meta robots tag or an X-Robots-Tag HTTP header; and its canonical tag should point to itself rather than to another URL.
These signals are easy to get wrong without noticing. A staging setting copied to the live site can add noindex to every page; a plugin can add a canonical pointing to the homepage; a server rule can send an X-Robots-Tag header that is invisible in the page source. The page still looks perfect in a browser, but it quietly disappears from Google.
Checking indexability in bulk is the quickest way to catch these problems across many pages, for example after a redesign, a platform change or a large product upload.
A page cannot rank if search engines are told not to index it. Stray noindex tags, robots.txt blocks and canonical tags pointing elsewhere are some of the most common — and most expensive — technical SEO mistakes, especially after redesigns and plugin changes.
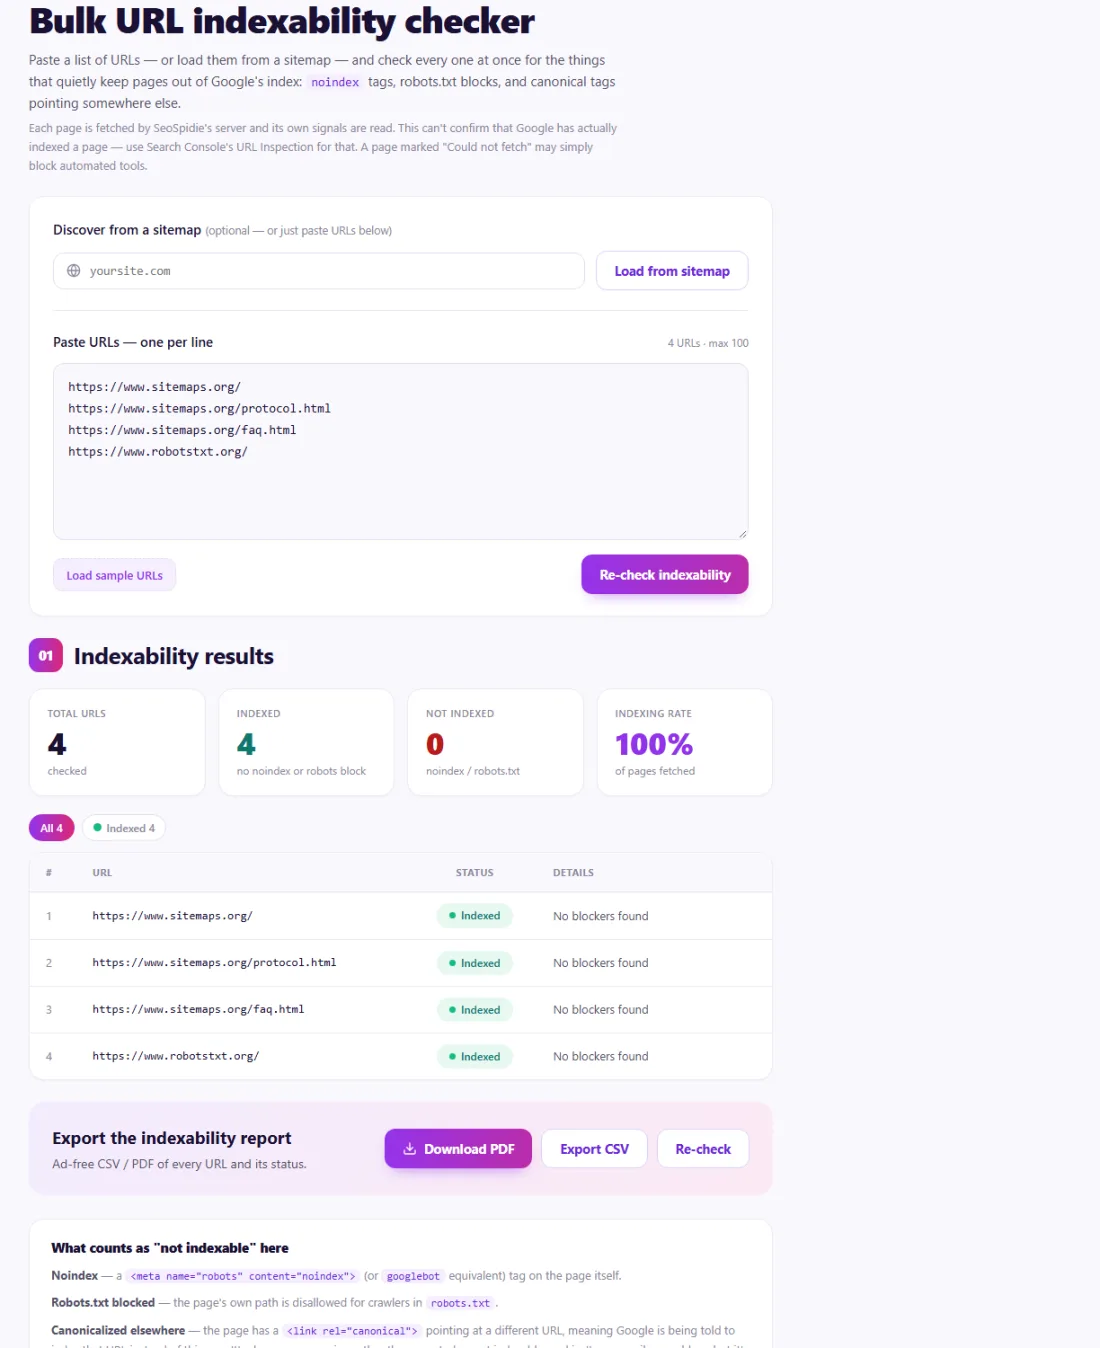
Pages marked indexable pass every check. For pages marked not indexable, the result shows why: an error status, a robots.txt rule, a noindex directive or a canonical pointing elsewhere. Decide for each page whether that is intended — thank-you pages and internal search results are often noindexed on purpose.
For pages that should rank, remove the blocking signal at its source, then request indexing in Google Search Console. Pages usually return to the index within days to a few weeks.
An outdoor clothing store in Germany launched a new theme, and over the next month organic visits to product pages dropped by almost half.
The owner loaded the product URLs from the sitemap into the Bulk Indexability Checker. Every product page was marked not indexable: the page source looked fine, but each response carried an X-Robots-Tag: noindex header copied from the staging server's configuration. After the host removed the header, the owner re-ran the check, saw every page marked indexable, and requested indexing for the top products in Search Console. Traffic recovered over the following weeks.
Robots.txt stops crawling; noindex stops indexing. To keep a page out of search results, allow crawling and use noindex, because search engines must fetch the page to see the noindex.
An HTTP header that can carry the same instructions as a meta robots tag, including noindex. It is invisible in the page source, so it is easy to miss without a header check.
Usually days to a few weeks. Requesting indexing in Google Search Console for important pages can speed things up.